Solving real-world artificial intelligence - whether for autonomous driving, real-world robotics, or advanced reasoning - requires an almost unfathomable amount of computational power. To meet this challenge, Tesla has been developing its own custom AI training hardware while simultaneously purchasing hardware in the open market.
Now, the next-generation Dojo 2 chip has reportedly entered mass production with the world’s largest semiconductor manufacturer, TSMC. While many may consider this a side quest, expanding Tesla’s computing base will be necessary to achieve exascale supercomputing, which will be crucial for all of Tesla’s AI ambitions.
Elon Musk called Dojo 2 “a good computer,” and then followed up with a classic computer performance joke - Dojo 2 can indeed play Crysis at a billion frames per second.
Can play Crysis at a billion frames per second
— Elon Musk (@elonmusk) July 12, 2025
Exascale AI: FSD, Optimus, and More
While Tesla has effectively utilized powerful third-party GPUs to train its models to date, the Dojo supercomputer is a ground-up, application-specific solution designed for a single purpose. It will efficiently process massive amounts of video data for training neural networks. The Dojo 2 chip itself is the key that unlocks this potential.
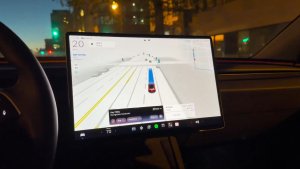
Dojo 2 will train the vision-based neural nets that FSD relies on, allowing Tesla to process video from its massive global fleet of vehicles even faster. As Tesla continues to improve FSD, one of the biggest challenges has been the intake of video for handling difficult edge cases.
Hundreds of thousands of miles of training data may pass by before an edge case is identified and trained on, but it all needs to be analyzed, labeled, and processed, which is key for Dojo 2. Each new useful piece of training data will help Tesla proceed down the march of 9s, making FSD just that little bit better every time.
This process requires massive amounts of compute and training time - but it is an absolute necessity to improve FSD. Of course, this goes beyond just FSD in vehicles. Tesla’s humanoid robot, Optimus, also runs on FSD to navigate and interact with the physical world.
While it may be a custom version of FSD, it remains FSD at its core, which means the same neural nets that analyze the environment and build a 3D map of the world for your car perform the same work for Optimus.

Custom Approach to AI Hardware
Dojo 2’s power doesn’t just come from raw compute; it comes from a series of architectural choices that make it excel at training FSD and differentiate it from general-purpose hardware, or even other AI-specific hardware.
To this end, Tesla is using TSMC’s new Integrated Fan-Out with Silicon-on-Wafer (InFO-SoW) packaging technology. For massive AI workloads, heat and the speed at which data moves between chips are often the biggest bottlenecks.
This new packaging technique allows for high-bandwidth connections directly between processing dies, which lowers latency and dramatically improves heat dissipation, all key to building massive and dense compute clusters.
Unlike general-purpose chips, Dojo 2 is designed with a custom instruction set, specifically built to train FSD. The cores are specifically made to accelerate the exact mathematical operations, like matrix multiples and systolic arrays, which form the backbone of Tesla’s vision-based neural networks.
By building its own hardware, Tesla can then integrate its own software and compilers directly with the silicon, optimizing for specific workloads and avoiding the performance penalties that can result from using third-party software, such as Nvidia’s CUDA.
The start of Dojo 2 may seem like a side quest for some, but it’s actually a key step for Tesla’s AI technologies that give them an advantage over the competition using off-the-shelf hardware. They’ll need to continue investing in custom hardware to improve FSD at a reasonable pace, rather than the current glacial pace we’ve seen over the last few months.